How passage search works
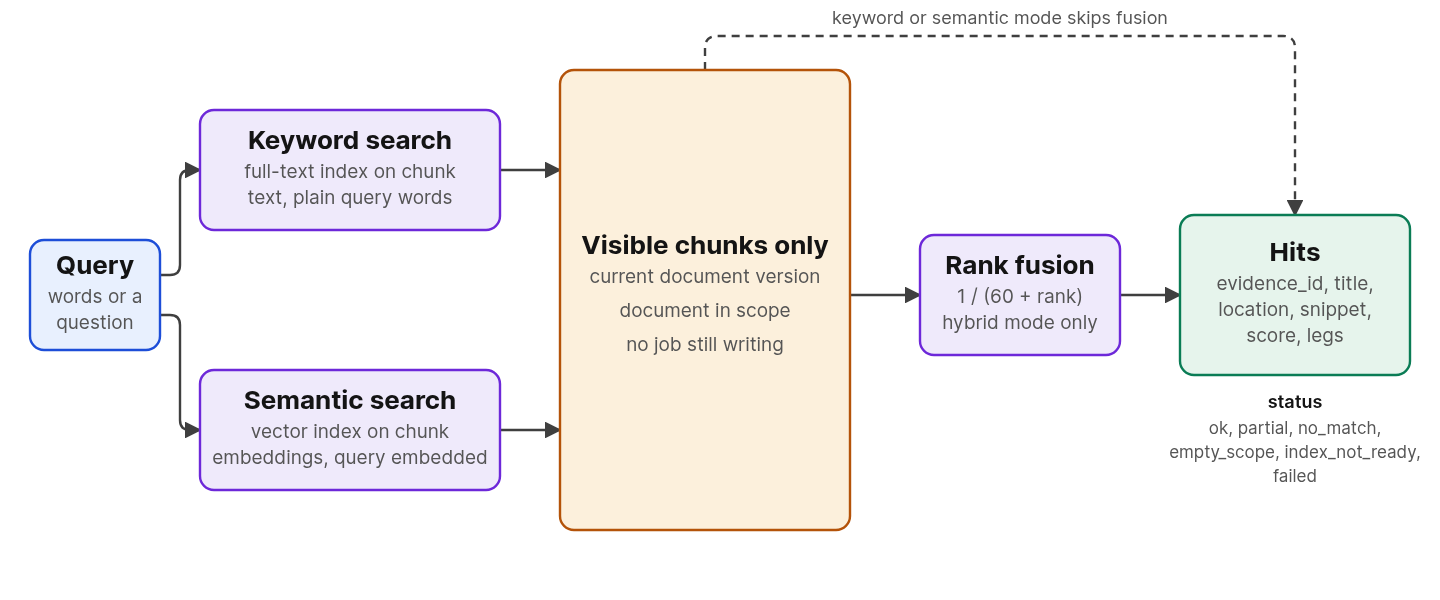
Passage search runs a keyword search, a semantic search, or both over the chunks of your documents. Each search asks an index for candidates, drops the chunks the caller may not see, and ranks the rest. Hybrid mode then fuses the two rankings into one list.
The steps of a call
- The call checks the scope. An empty scope returns
empty_scopewithout a search. - The call checks that each index the mode needs exists and is online. A missing or offline index returns
index_not_ready. Keyword search needs the full-text index on chunk text, and semantic search needs the vector index on chunk embeddings.Graph.opencreates both indexes. - Each search asks its index for
limitcandidates and drops the chunks that are not visible. - When fewer than
limitcandidates are visible, the search asks again with four times as many candidates, up to 1000. The result setstruncatedwhen the ceiling is reached beforelimitvisible chunks are found. - In
hybridmode the call fuses the two ranked lists. In the other modes the order of the single search stands. - The call builds one hit for each chunk, with the evidence id, the document key, the title, the location, a preview of the first 240 characters, the score, and the searches that found it.
Which chunks are visible
A chunk is visible when it has an open HAS_PART edge from a current document version, belongs to a document in scope, and no ingestion job is still writing it. These rules are part of each search query, so a hidden chunk never takes a result slot. Superseded text and text outside the scope cannot appear in a result.
Keyword search
The call reduces the query to its word characters, lowercases them, and joins the words with spaces. Lucene operators, field names, quotes, and escapes never reach the parser, so the query AND (policy becomes the two plain terms and and policy.
Neo4j reads the terms with Lucene's default operator, which is OR. A chunk that holds any query word can match. The full-text score ranks chunks that match more of the words, or rarer words, higher.
Quotes do not make a phrase, - does not exclude a word, and AND does not require both words.
Semantic search
The embedder you pass embeds the query, and the vector index returns the chunks with the nearest embeddings. The index measures nearness with the distance function that Embedder.distance declared when ingestion created the index.
By default a chunk is embedded with its heading path in front of its text, so a query that matches a section title can find the passages under it.
The embedder must be the model that ingestion used. The vector index fixes the number of dimensions, and a different dimension makes the semantic search fail. Two models with the same dimension look identical to the index, so keep the embedding model setting the same for ingestion and search.
The semantic search has no similarity threshold. It returns the nearest chunks for every query.
Hybrid fusion
Reciprocal rank fusion scores each chunk from its rank in each list and ignores the raw scores. A chunk at rank r in a list adds 1 / (60 + r), and a chunk in both lists adds both terms. The call sorts by fused score and breaks ties by evidence id, so the order is stable.
The hybrid search for "How soon is customer data erased?" in Passage search shows the arithmetic. The retention chunk ranks first in both searches, so it scores 1/61 + 1/61, which prints as 0.0328. The route planning chunk ranks second in the keyword search and third in the semantic search, so it scores 1/62 + 1/63, which prints as 0.0320. The table chunk appears only in the semantic search, at rank 2, so it scores 1/62, which prints as 0.0161. A chunk that two searches rank well beats a chunk that one search ranks well.
Each search contributes at most its top limit visible chunks, so a chunk beyond that depth in one list adds nothing from that list. Scores differ in scale between modes, so a score from one mode does not compare with a score from another.
Design choices
Search runs over chunks. A chunk is small enough to read and to cite, and its evidence id names exact text. Chunking describes how documents are cut.
The call strips query syntax. A query comes from a model or a user and cannot change how the index parses it. Plain words remove a class of malformed-query failures and give the same behavior on every surface.
Fusion works on ranks. A full-text relevance score and a vector similarity differ in scale and distribution, and a rank compares across searches. A fused score has meaning only inside one call.
A failed search changes the status. A hybrid call that dropped the failed half without saying so would look like a complete call with fewer hits. The partial status and the failures list show the gap, so a caller can retry or warn.
Related
- Passage search lists the inputs, the result fields, and the statuses.
- Chunking sets the size and boundaries of the chunks that search returns.
- Retrieval compares keyword, semantic, and hybrid search with the other strategies.